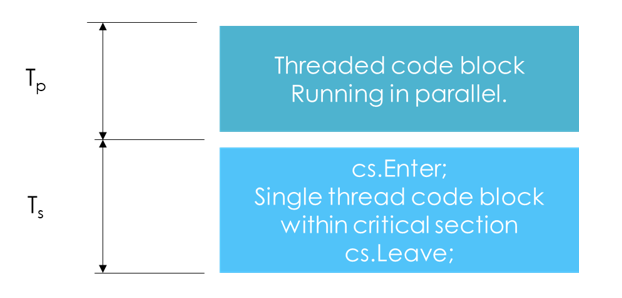
Fair Critical Section
A critical section is fair if all threads exit in the same order in which they arrived — avoiding the 2-3x performance penalty unfair locks cause on many-core CPUs.
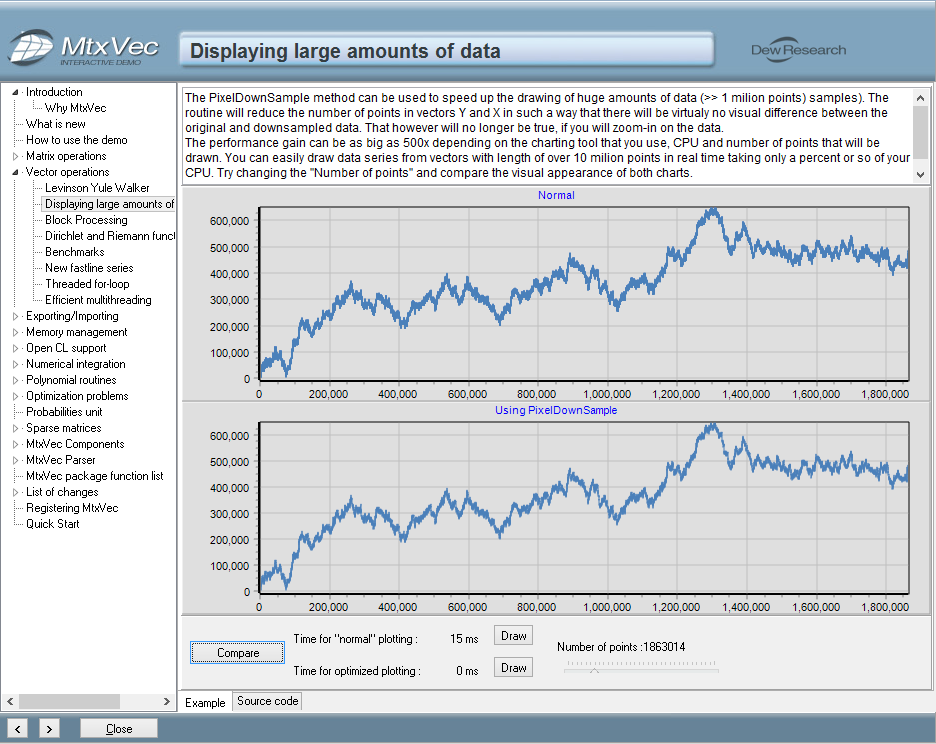
Brute-force exact KNN
K-NN is the grandfather of AI algorithms. With our implementation we accelerate KNN to performance levels not imaginable before — a 1000-2000x speed-up for very large problems.

Multi-precision code
Select algorithm precision (single or double) at runtime — halve the memory usage and double the speed of execution without writing separate code paths.

Getting up to speed
Code vectorization is where high performance computing starts
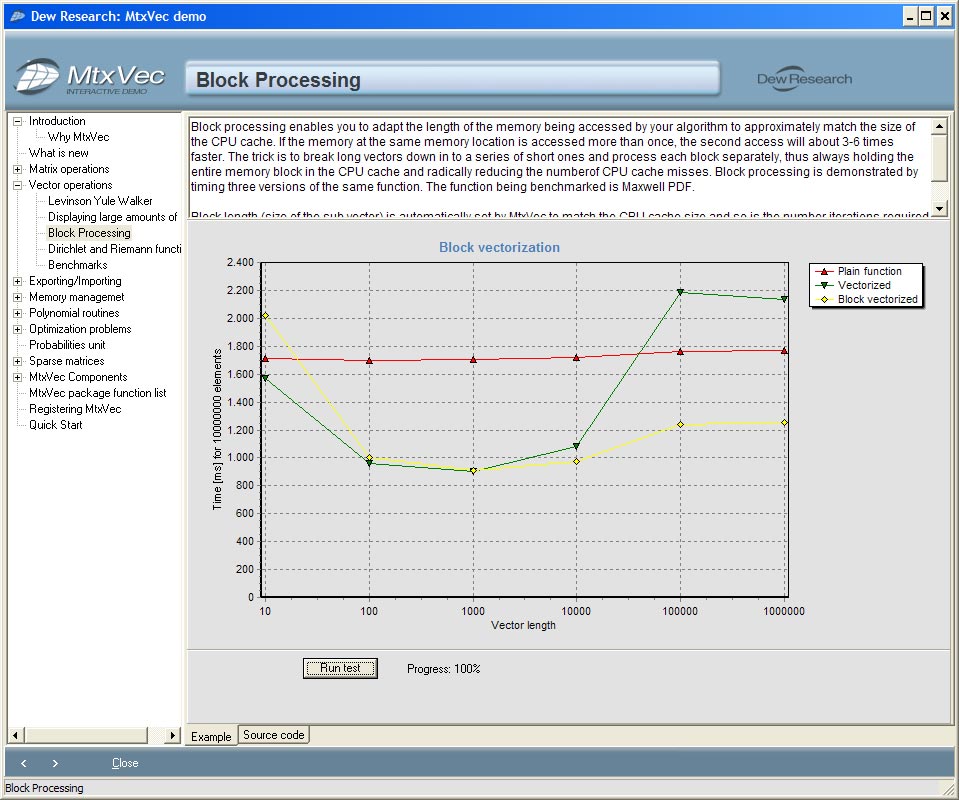
Block processing
Second step of code optimization after applying code vectorization is called block processing

Objects and numerics
Simplify the use of numerical algorithms
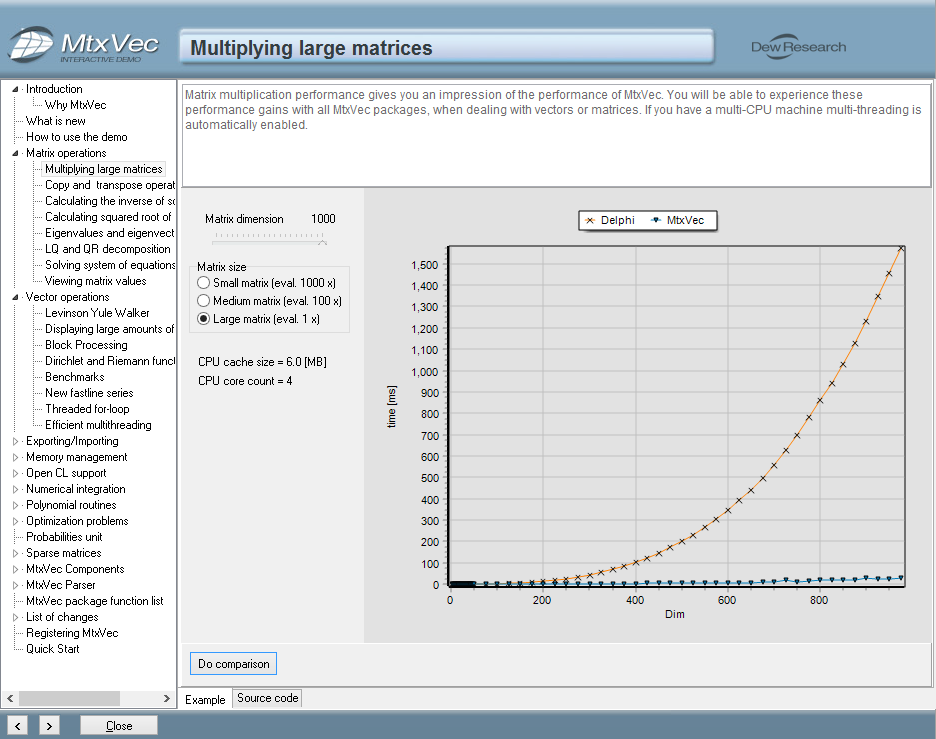
MtxVec encapsulates LAPACK
The computing standard for linear algebra is included

Math functions and speed
MtxVec includes vectorized functions working on complex and real numbers

Super conductive memory manager
MtxVec's vector and matrix objects are super conductive across threads — multiple threads allocate and free them without contention or synchronization locks, enabling truly linear scaling on multi-core CPUs.

MtxVec expressions
It was Delphi 2006 that first introduced the ability to overload operators on records. This feature enabled MtxVec to add high performance support for using vectors, matrices and complex numbers in expressions.