Performance against Intel IPP VML
MtxVec provides AVX-512, AVX2, and SSE4.2 implementations. AVX2 and SSE4.2 cover both Win32 and Win64. AVX-512 covers Win64 only, so it contributes 76 cases, with 38 functions in two precisions.
The library is designed for balanced performance across AMD and Intel processors. The optimization process considered recent architectures from both vendors for each instruction set.
Open the interactive chart and hover over a row or focus it with Tab to see the exact timings, ratio, and case count.
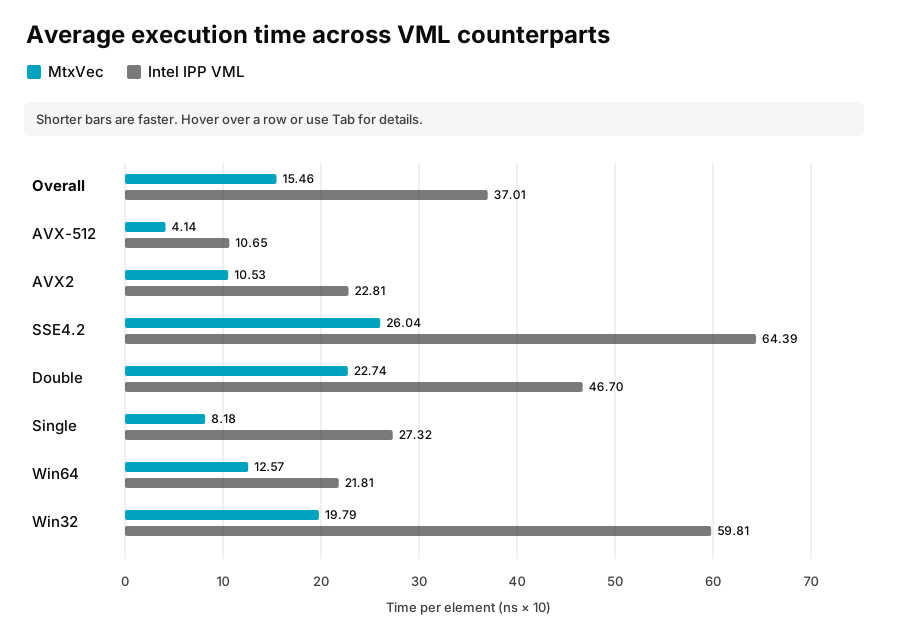
| ISA | AVX512 | 76 | 4.14 | 10.65 | 0.39x |
| ISA | AVX2 | 152 | 10.53 | 22.81 | 0.46x |
| ISA | SSE42 | 152 | 26.04 | 64.39 | 0.40x |
| Precision | Double | 190 | 22.74 | 46.70 | 0.49x |
| Precision | Single | 190 | 8.18 | 27.32 | 0.30x |
| Platform | Win64 | 228 | 12.57 | 21.81 | 0.58x |
| Platform | Win32 | 152 | 19.79 | 59.81 | 0.33x |
| Overall | 380 | 15.46 | 37.01 | 0.42x |
Each benchmark cell represents one function, precision, platform, and instruction-set combination. The ratio divides the mean MtxVec time by the mean Intel IPP time. A time of 15.46 in the table is 1.546 ns per element. Single precision showed the larger of the two precision-level gains, at 30% of the reference time, or a 3.34× speedup.
How the functions were timed
The L1 benchmark repeatedly processes a 1,024-element block that fits in L1 cache. The branch-prediction benchmark streams successive blocks of varied inputs from L2, reducing the benefit of repeating the same input pattern. Both tests time corresponding functions at the same instruction-set tier. Intel IPP VML is the timing reference for this comparison.
Individual results depend on the function and instruction set. In the branch-prediction benchmark, double-precision Pow on Win64 AVX-512 used 8% of Intel IPP’s time, while double-precision ErfInv on Win64 SSE4.2 took 2.14× Intel IPP’s time.
Numerical accuracy
A ULP, or unit in the last place, is the spacing between adjacent floating-point values near the result. The figures below are maximum measured errors for double-precision Win64 AVX-512, using high-precision mpmath calculations as the reference.
Ceil | 0.000 ULP |
Exp | 0.543 ULP |
Pow | 0.550 ULP |
ACos | 0.621 ULP |
Sin | 0.750 ULP |
Tan | 0.946 ULP |
Erfc | 0.997 ULP |
Complex-number vector math
MtxVec also provides vectorized complex-number functions. Separate measurements show speedups of around 5× for those functions. The table and chart above cover the real-valued functions.